Labs
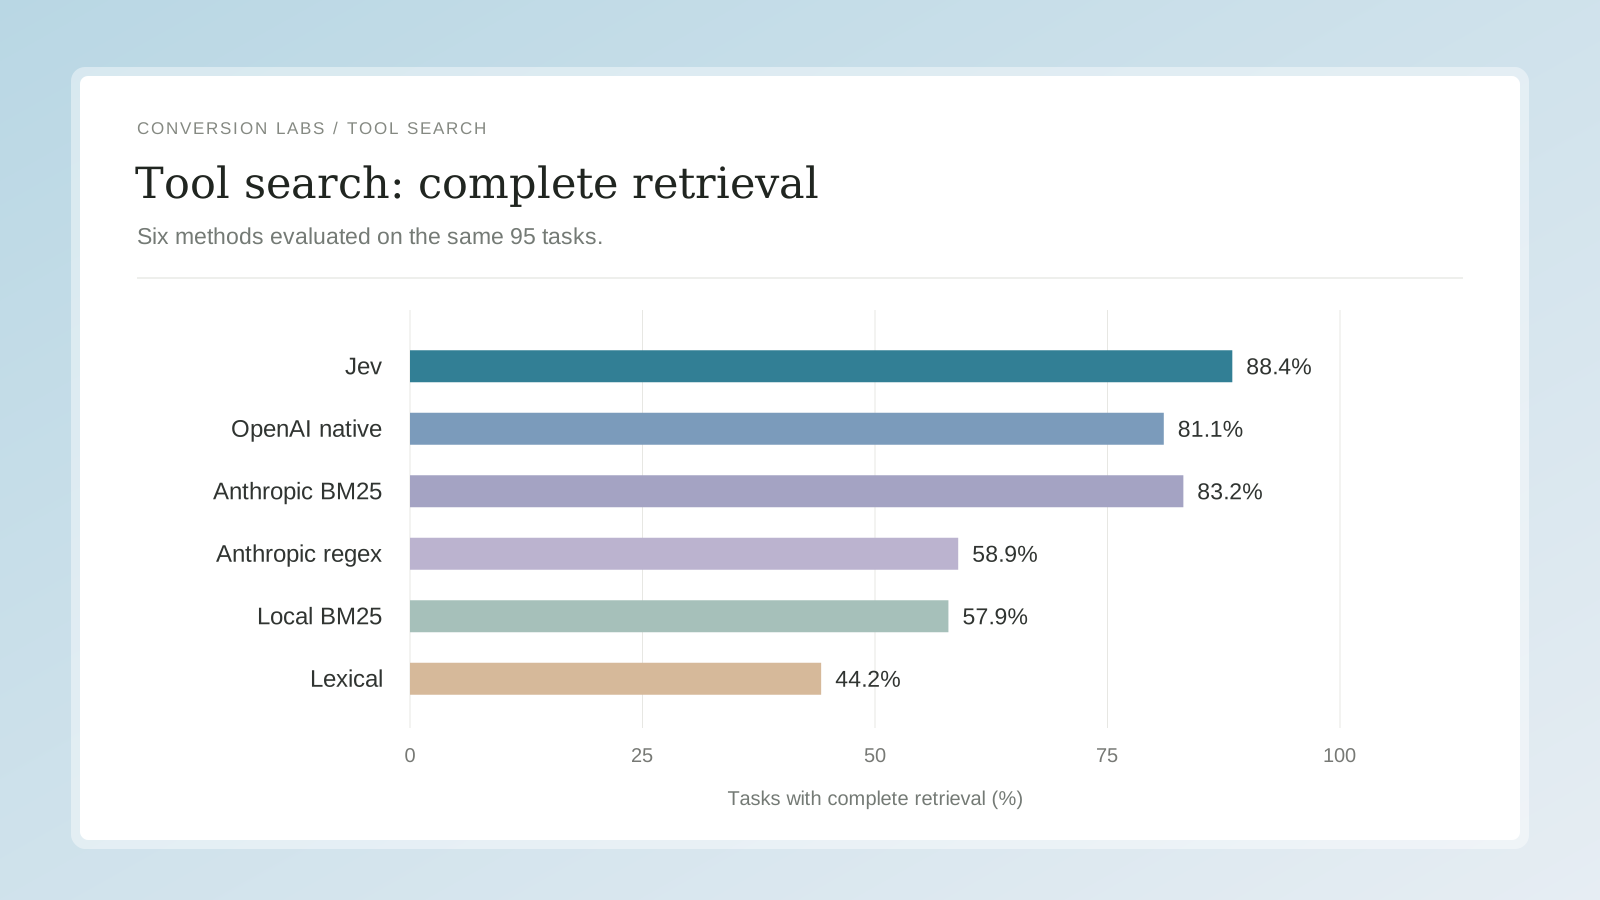
Jev made us take another look at tool search
How we used Jev to select tools for Conversion's agent, with benchmarks against lexical, BM25, and native tool search.
Sep 28, 2026 · 5 min read
Core MAP
Advanced Features
By role
Research, experiments and benchmarks from the team building the platform.
Labs
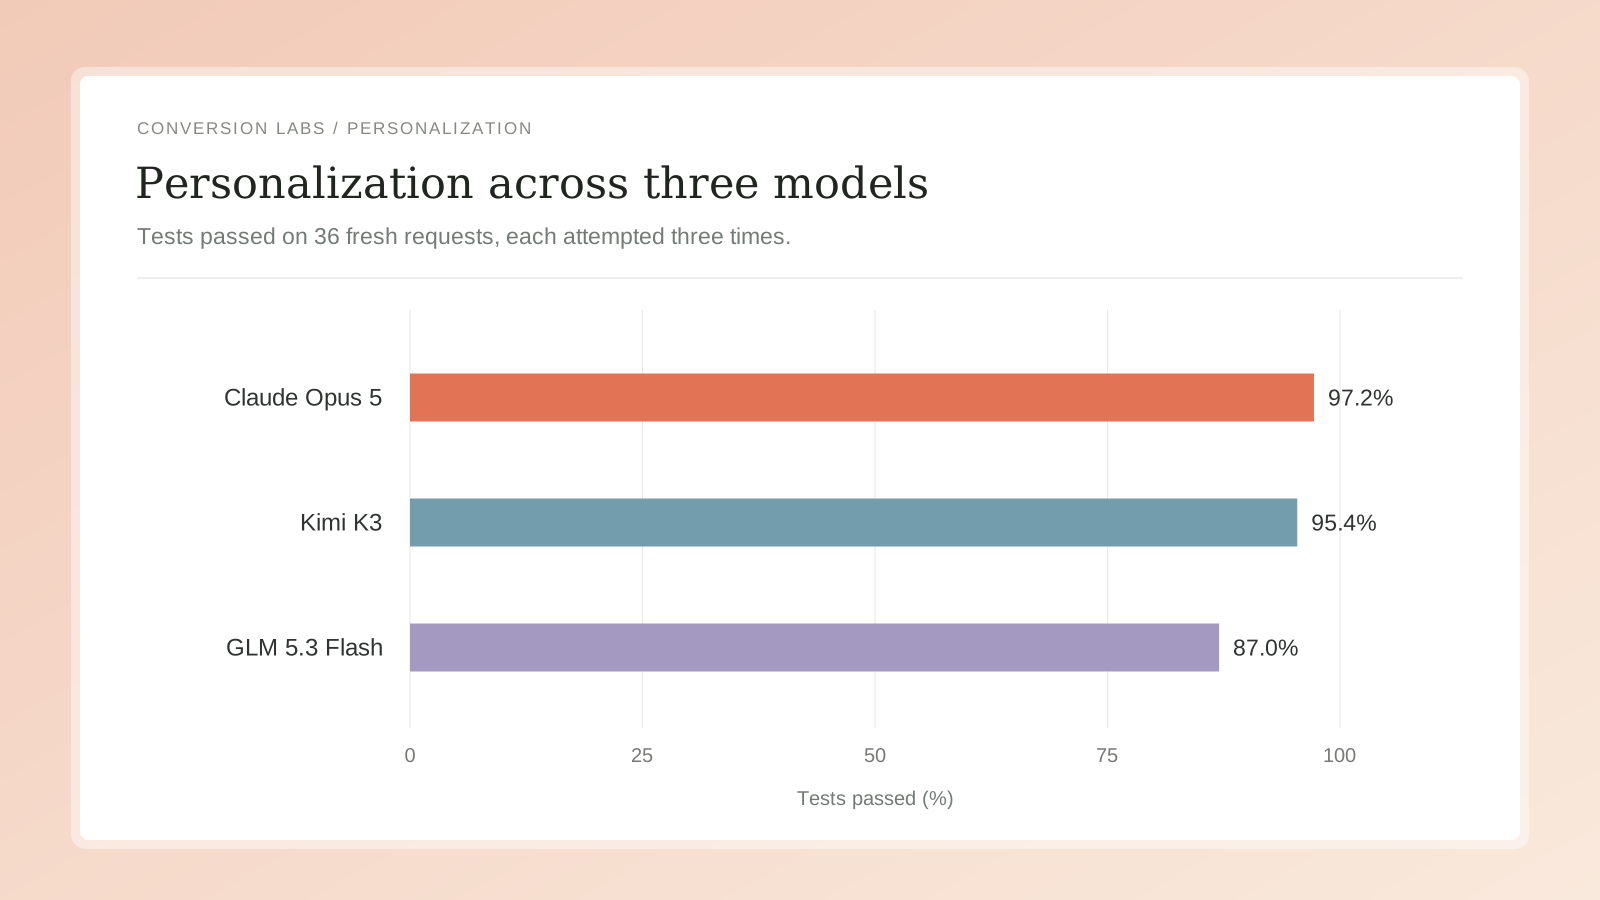
One-to-One: a benchmark for AI agents building personalized marketing content.
Labs (5)
Labs
How we used Jev to select tools for Conversion's agent, with benchmarks against lexical, BM25, and native tool search.
Labs
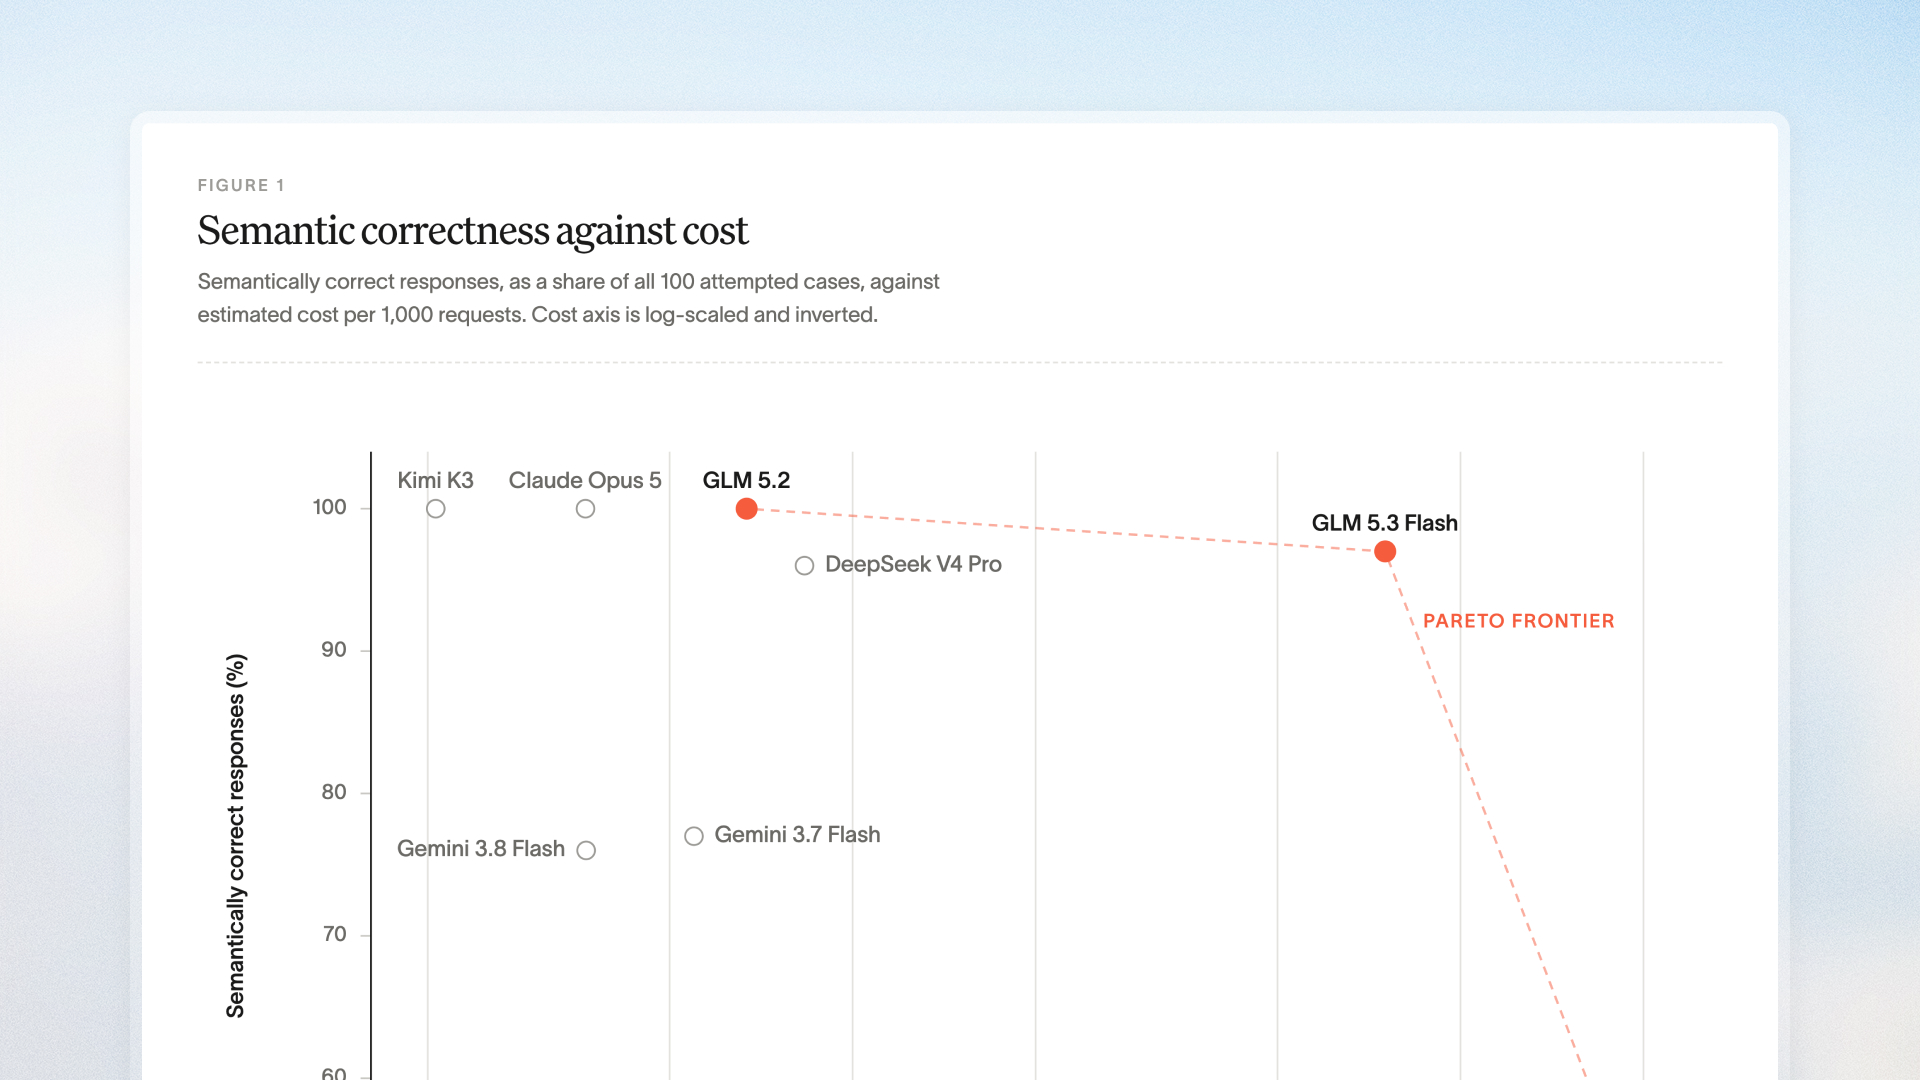
Our text-to-query agent went from 45 seconds on frontier models to 2 seconds on GLM 5.3 Flash, with the same accuracy at 1/20 the cost. This post describes the architecture, evaluation loop, and lessons learned.
Labs
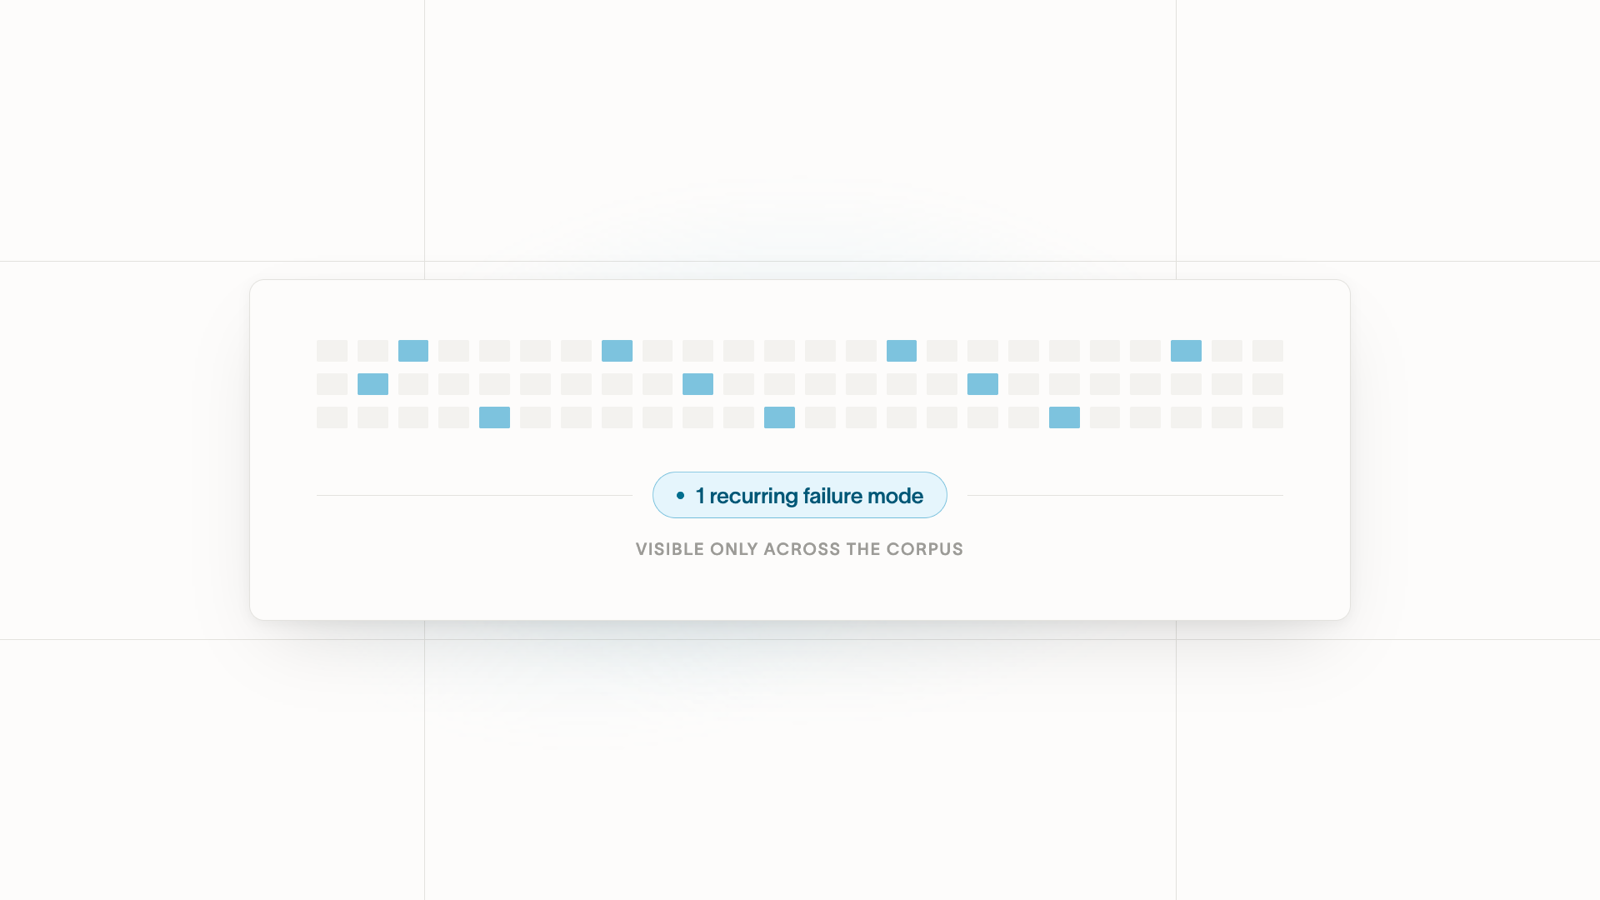
An observability pipeline that reads production traces at corpus scale, names recurring failure modes, and proves the fix held.
Labs
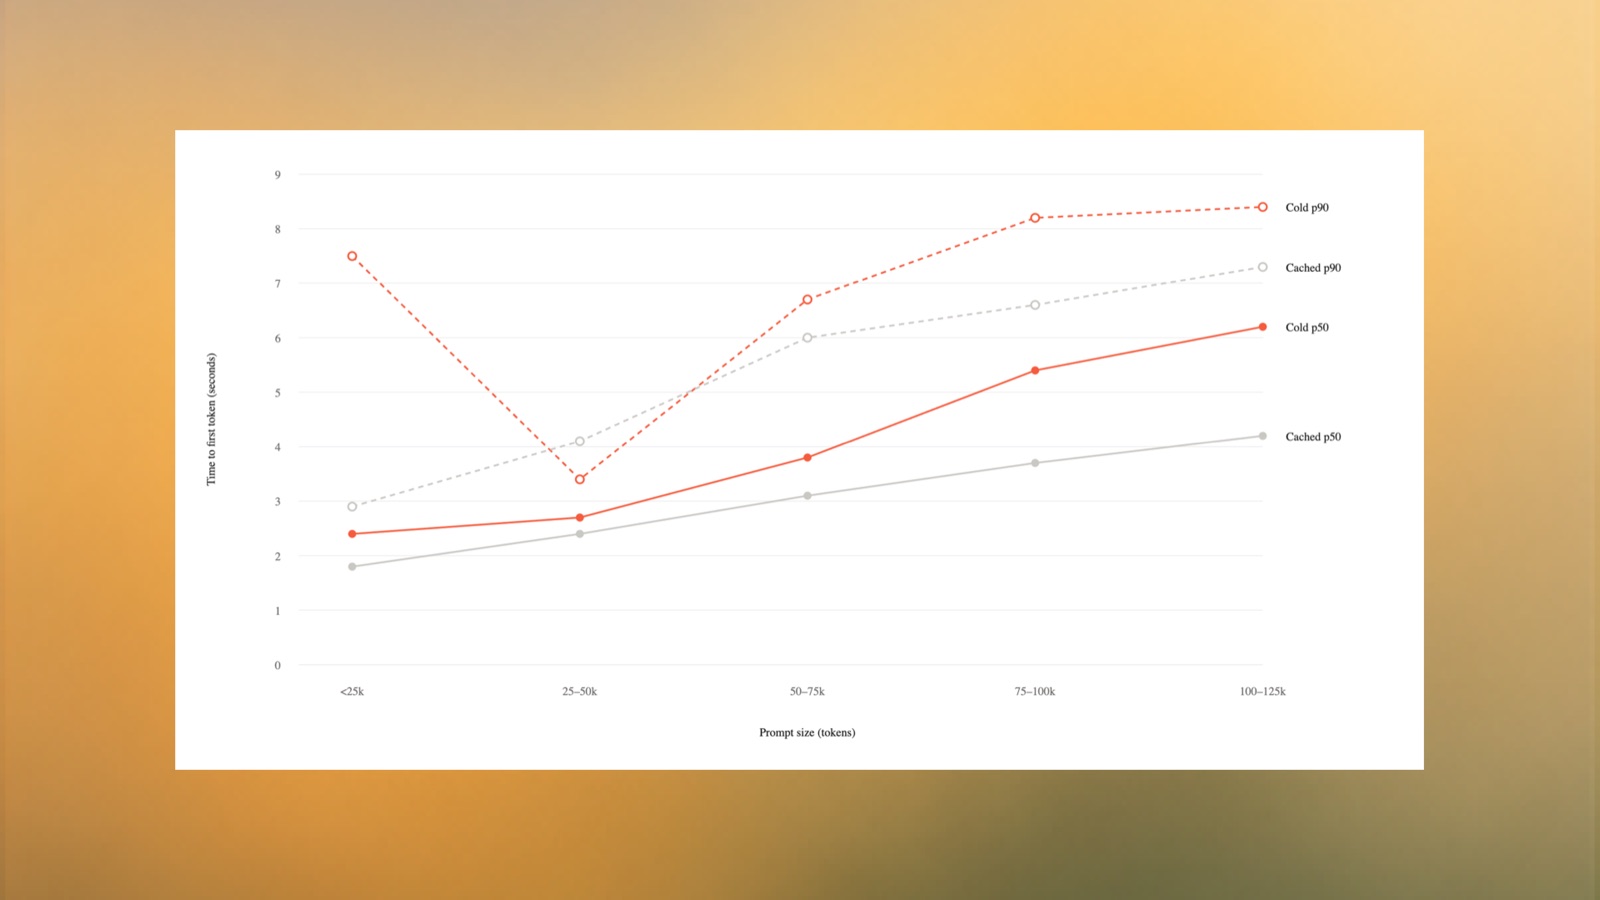
A median request carried 150,000 tokens. Most of our context work since comes down to one move, applied repeatedly.
Labs
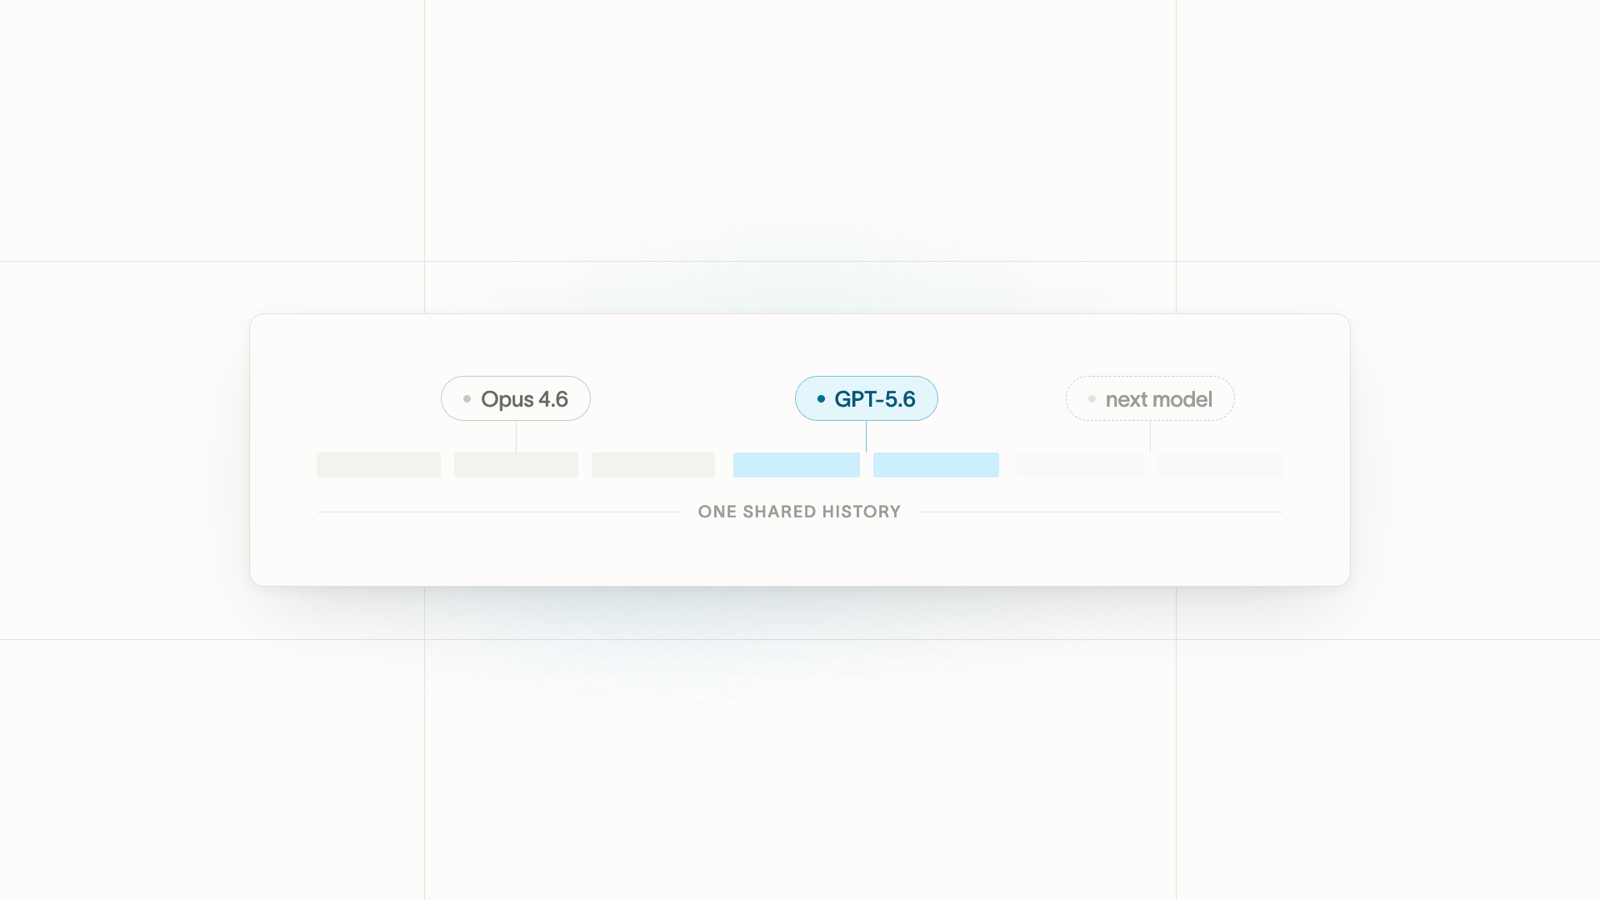
How and why we made our harness model-agnostic, and what per-turn portability actually cost us.